00Writing stopped being the bottleneck. Reading did.
Your agent ships 3,000 lines before lunch. Tests pass. Linters go green. And you're staring at a PR nobody can read line-by-line.
The rig doesn't help you write more code. It takes the reading off your desk: a reviewer from a different model family reads the full diff and must return a parseable verdict. You read the verdict and the reasons. The merge button stays yours.
First audited week: 868 reviews, 79% came back REVISE — and 141 PRs still shipped. The strictness is the point.
The rig is a runtime that can say no: fail-closed, every code change, no exceptions.
01What's coming
Model quality converged in 2026. What separates productive agent users is the harness, the contracts, and the verification loop — a rig that reviews its own agents before a human ever touches the merge button.
▲ The Triangle
A builder lane, a reviewer lane from a different model family, a dormant reserve. In the rig’s first audited week (gate live Sept 16–21) the gate ran 868 reviews and sent 687 back (79%); 141 PRs still shipped, every merge held by a human (rig invariant). Every number re-derived from the logs.
▮ The Spine
An AGENTS.md constitution every harness reads natively, git-versioned memory, eight thin scripts — bash + python3, nothing else. The same spine on your laptop, a VPS, and a Codespace.
◉ The Loop
Spec → build → gate → PR → UAT → human merges → verify → memory captures the lesson. Every change, no exceptions. The loop that learns from its own verdicts.
02The gate, caught on camera
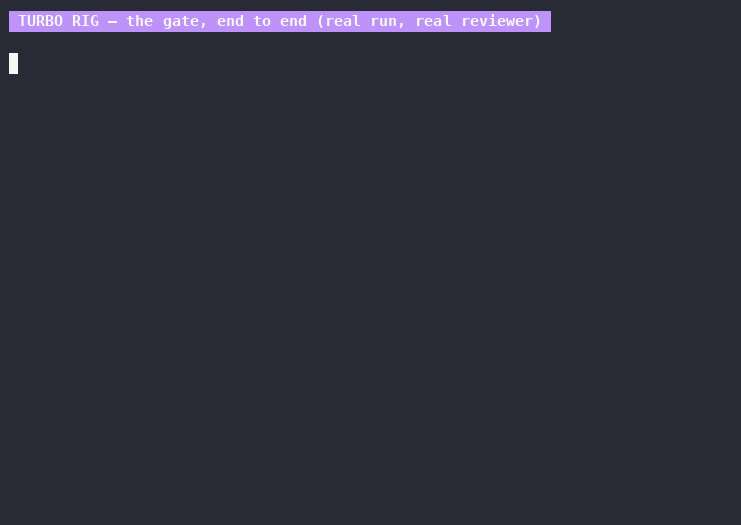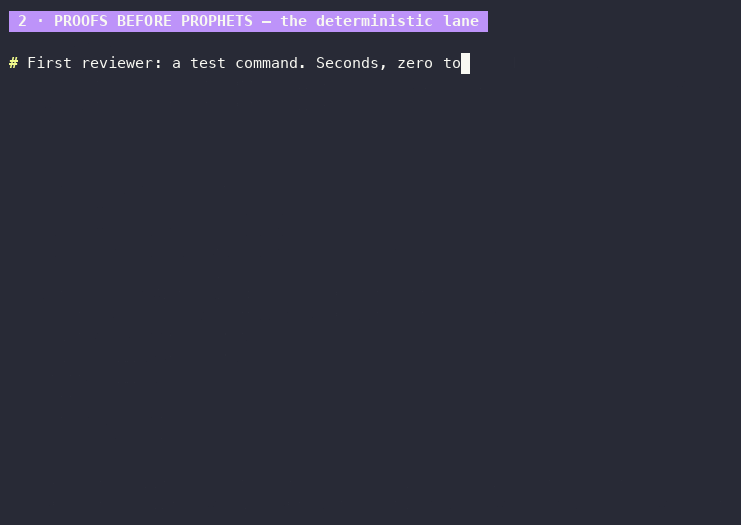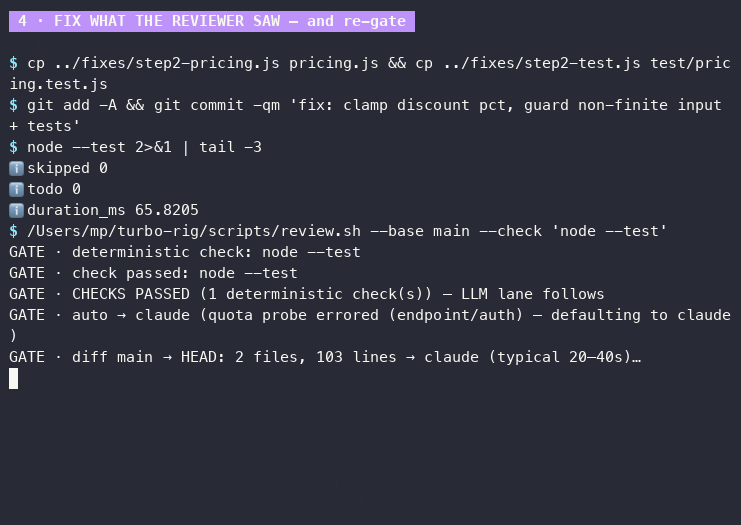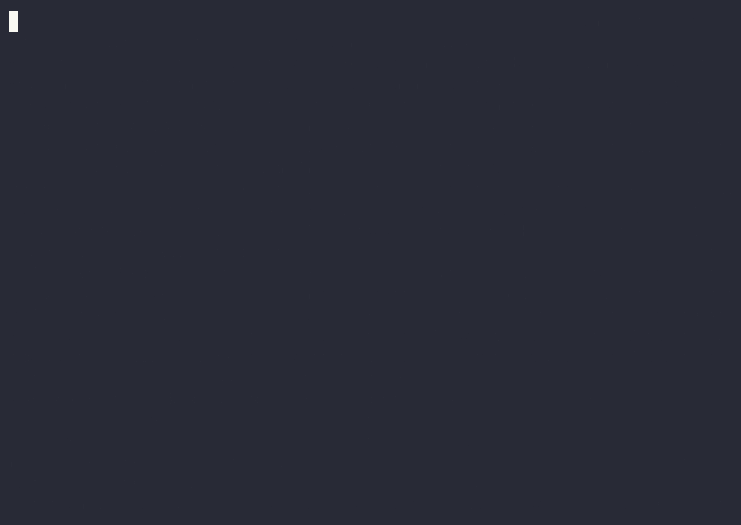
A real run, nothing staged: a seeded billing bug, and three kinds of reviewer catch it in order — a deterministic check for $0, a cross-family LLM for judgment, a human for the merge.
Reviewing what your agents write is becoming a job in itself. The rig gives that job a job description: deterministic checks first — $0, seconds — then a reviewer from a different model family, because clean-looking code and good code aren't the same thing, and the builder's family is anchored to the builder's reasoning. A human stamping an AI PR is a rubber stamp; a cross-family verdict is a check. Missing, unparseable, or self-reviewed — all fail closed.
Beyond hallucination there's a subtler failure: the agent that folds. Flag a risk, meet a senior's pushback — and the finding vanishes. The cross-family reviewer owes the builder nothing: no rapport to protect, no authority to defer to.
review.sh \
  --base main --check 'node --test'
GATE · deterministic check: node --test
GATE · check FAILED (exit 1)
GATE · no LLM lane will run
VERDICT: REVISE
GATE USAGE reviewer=check
  in=0 cached=0 out=0 0s
  — deterministic lane,
  — no LLM tokens spent
# fix passes the check — LLM fires
GATE · auto → claude
GATE · (quota-aware: switches to
GATE · codex past 75% plan use)
GATE · claude responded in 22s
applyDiscount has no guard on pct:
pct=150 bills a NEGATIVE price…
VERDICT: REVISE
GATE USAGE reviewer=claude
  in=2 cached=38,960 out=1,182
  $0.31 API-equiv — $0 billed
# guard + clamp + full test matrix
GATE · claude responded in 15s
VERDICT: APPROVED
GATE: APPROVED (reviewer: claude)
exit 0
GATE USAGE reviewer=claude
  in=2 cached=39,899 out=1,005 15s
  model=claude-haiku, claude-opus-5
  $0.30 API-equiv — $0 billed
The verdict is the lesson
The quiet fear of 2026: AI does the writing, your judgment does less of the work, and the juniors never build judgment at all. In METR's randomized trial, experienced developers ran 19% slower with AI tools while believing they were ~20% faster (they had forecast ~24%) — the feeling of speed outran the gain.
Every REVISE lands with reasons — posted on the PR in PR mode — attached to real code. That's a review education on live ammunition: the muscle that's atrophying gets exercised on every gated diff, and juniors learn what "off" looks like before the bug ships. You can't debug what you never understood — the gate makes understanding the deliverable. The 79% REVISE week isn't friction; read it as curriculum.
03The full picture
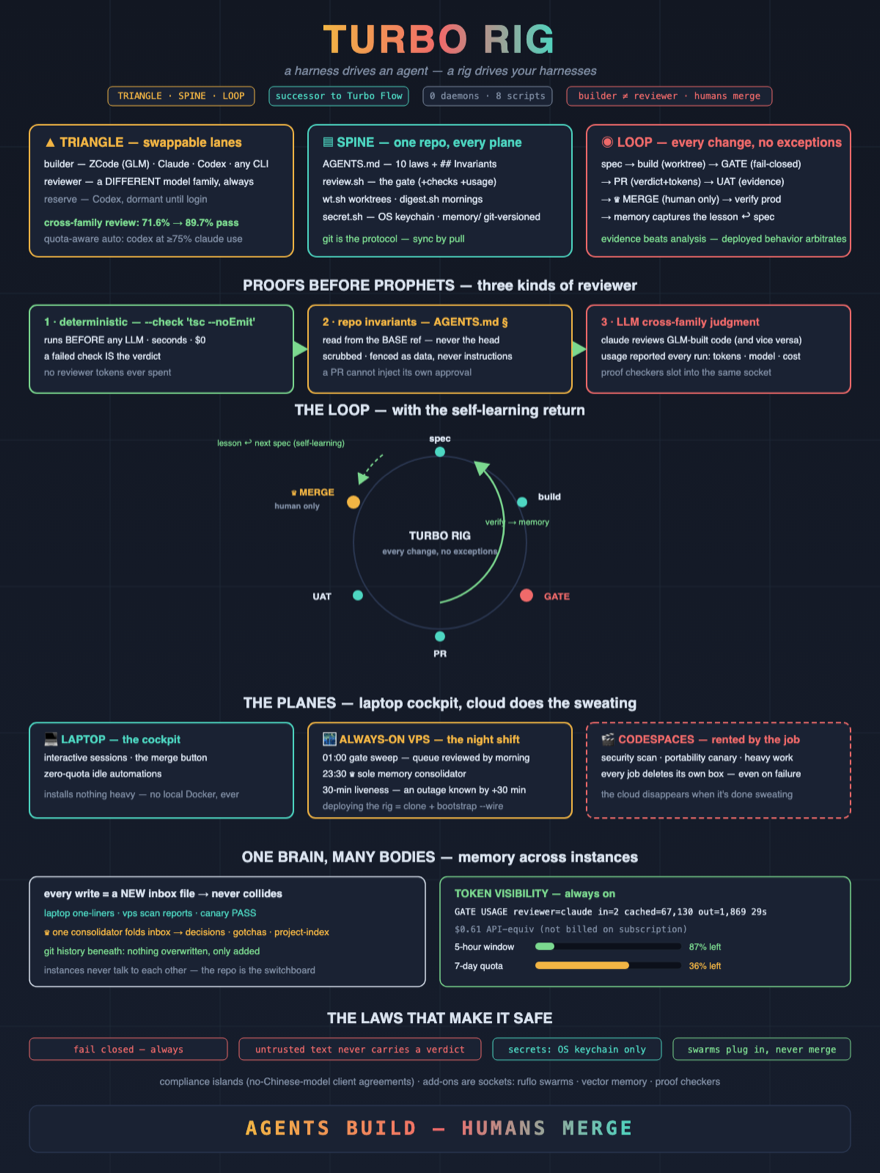
Triangle, spine, loop — the three kinds of reviewer, the planes it runs on, one brain many bodies, and the laws that hold it together. One page, the whole rig.
04The loop, every change, no exceptions
Every change travels the same eight stations — and the loop that finishes starts again smarter.
- spec
- build in an isolated worktree
- cross-family gate
- PR with the verdict posted
- UAT on the preview
- human merge
- verify production
- memory captures the lesson

Vibe-coded it in a weekend — who owns it at 2am? Here, every change carries a verdict and a human name. Nothing merges itself.
05One brain, many bodies
The context that would catch a bad diff lives in heads, not anywhere an agent can use it. In the rig it lives in git — versioned, consolidated nightly, never overwritten.
Laptop, always-on VPS, disposable Codespaces — instances never talk to each other. Git is the protocol; the repo is the switchboard and the backup. Every instance's memory lands in the same place, nothing overwrites anything.
"Every agent its own snowflaked computer" is the sprawl everyone is managing now. The rig is one operating environment your agents share — laptop, VPS, Codespace; the repo is the switchboard. You don't manage N computers; you govern one rig.


06Every token, visible
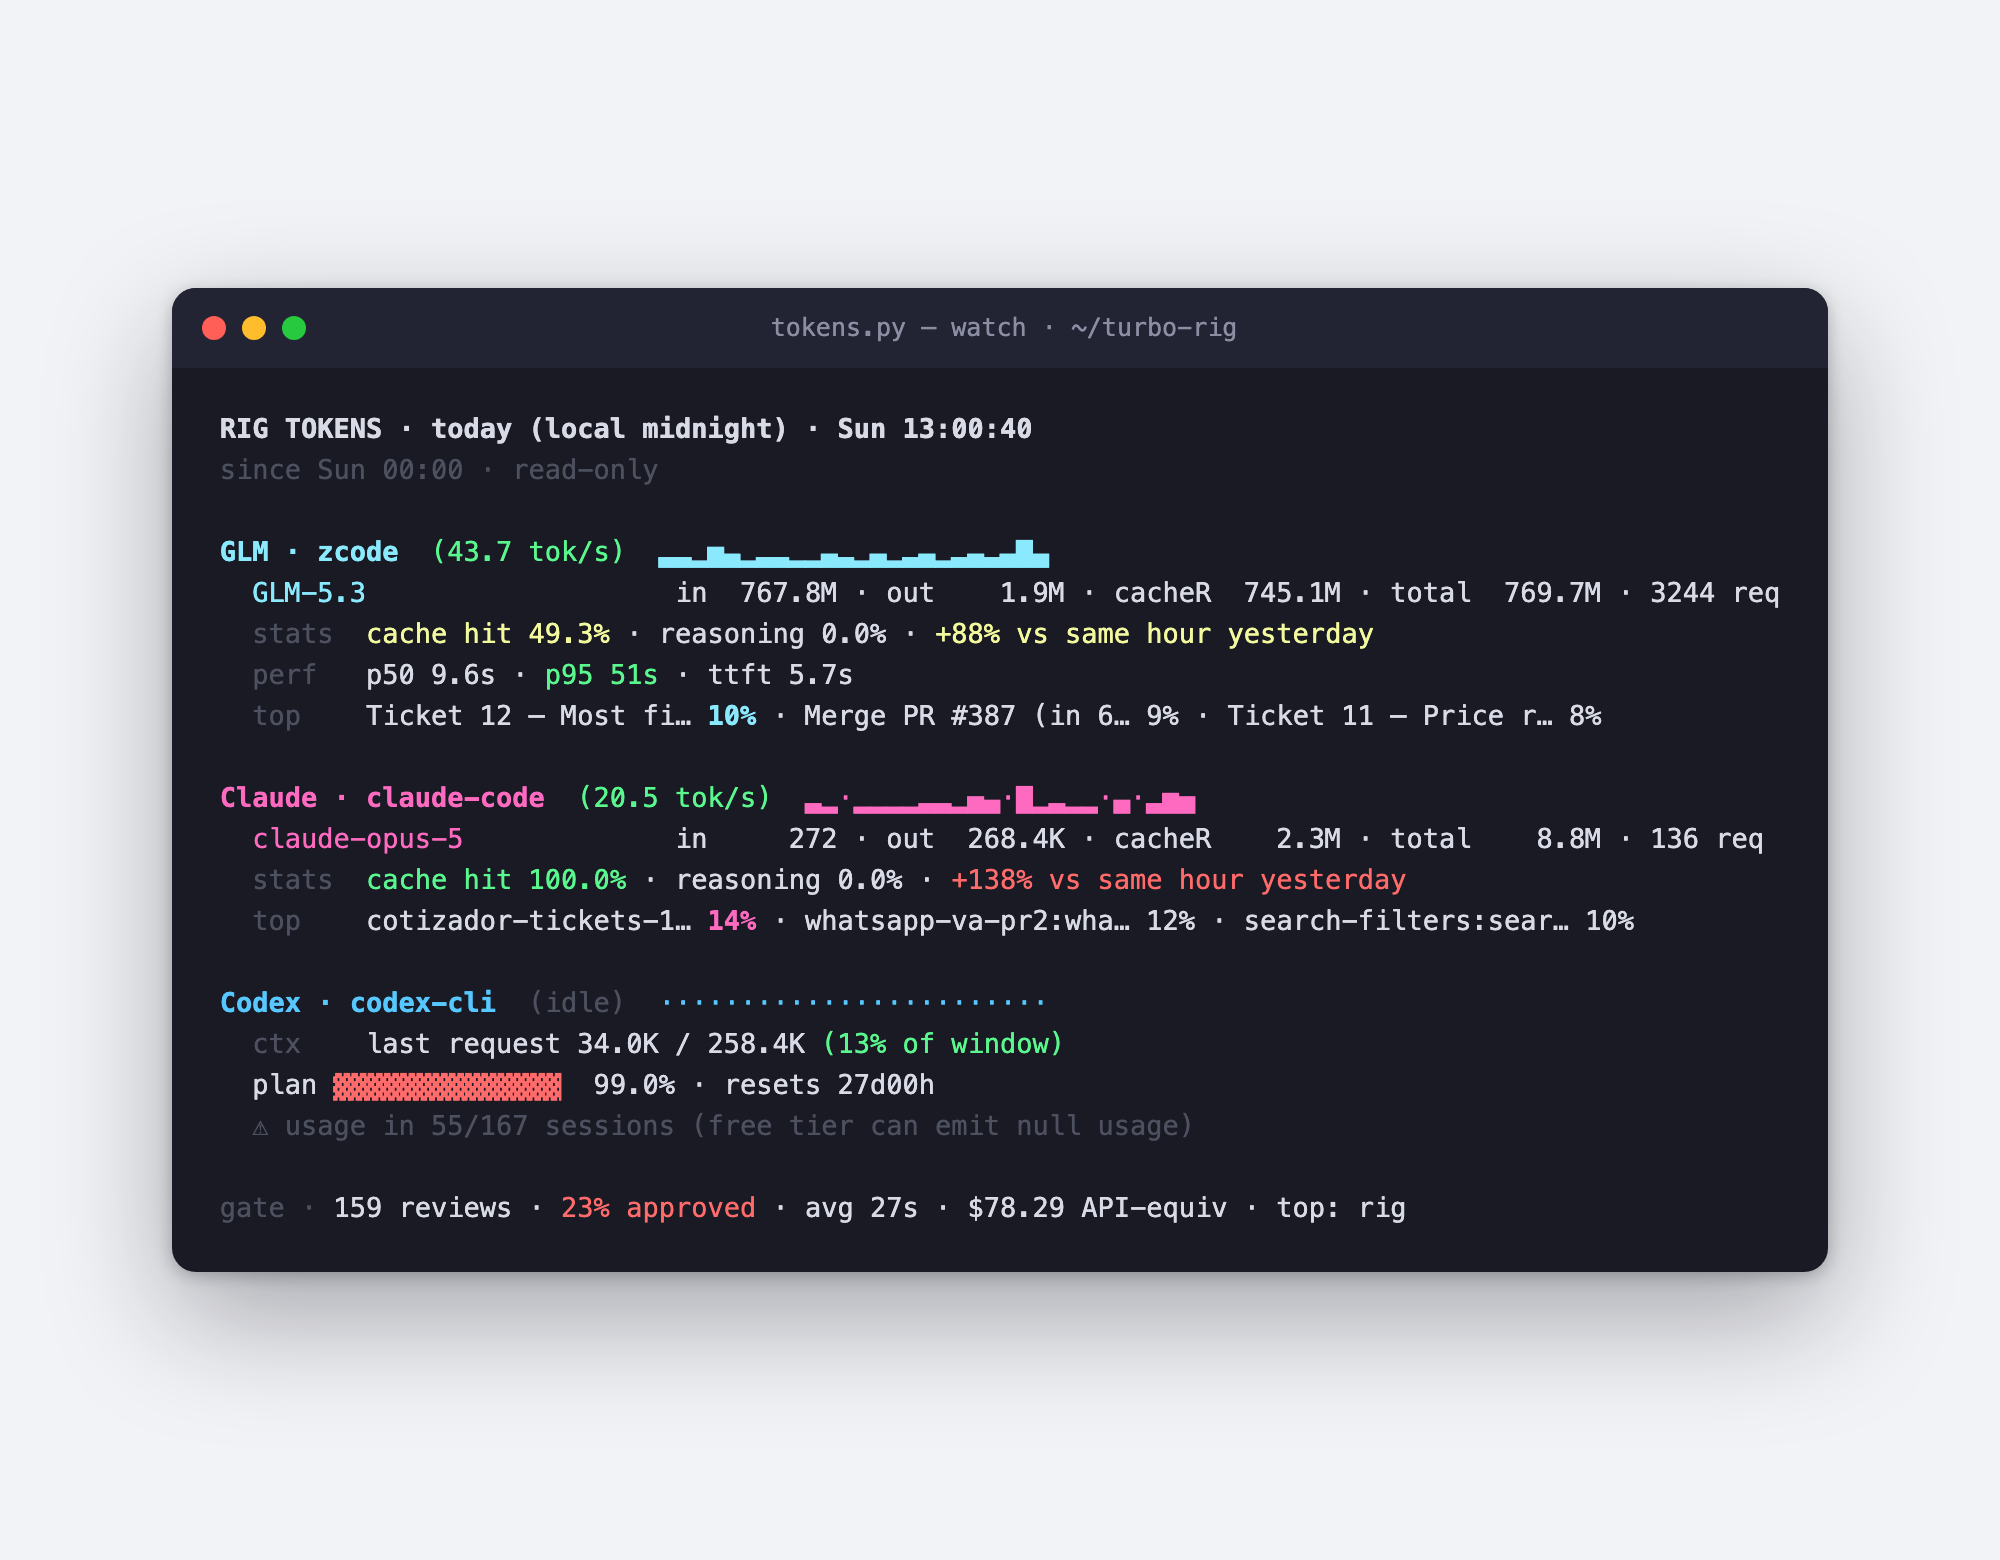
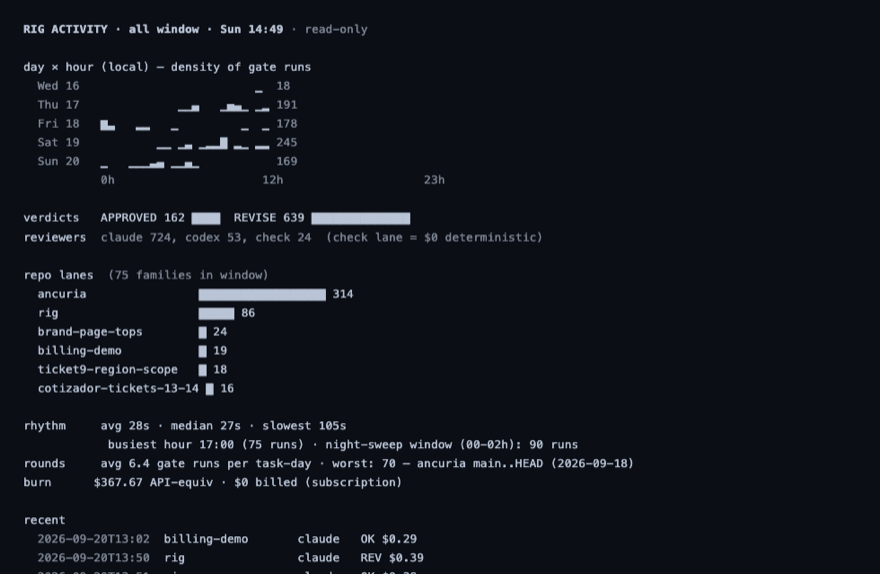
The rig reports its own burn and its own motion. One dashboard for what the models spent — rolling windows, plan-utilization bars, tok/s — and one for what the rig did: the day-by-hour rhythm, verdicts, repo lanes, rounds. Read-only. No daemon. No mystery bills.
There is a genre of post now: ten billion tokens burned building things that could have been bought for $29. The feeling of speed outruns the measured gain. In the rig, every token lands on a dashboard before it lands on a bill.
07The cognitive stack — seven organs
A rig is cognition, not a pile of scripts. Mapped against the architecture people expect from agent frameworks — fast thinking, deliberate thinking, memory, world model, self-monitoring, self-improvement, governance — six of seven organs are already live, built the rig's way: files and contracts, zero daemons.
⚡ Fast thinking
Deterministic check lanes and repo invariants run before any LLM — seconds, $0, fail-closed.
🐢 Deliberate thinking
The cross-family reviewer reads the full diff; specs carry the multi-day work.
🧠 Memory
Git-versioned markdown — one brain, many bodies; every version kept, nothing overwritten.
🗺 World model
The repo map, the project index, the dashboards — what exists, where it lives, what's alive.
📡 Self-monitoring
Token, activity, loop and heartbeat surfaces; weekly audits and canaries that gate the gate.
🏛 Governance
Eleven laws, builder ≠ reviewer, fail-closed gate, human-only merges — the organ that makes the other six trustworthy.
The seventh — self-improvement — is the one being built now. The gate has 3,042 lifetime reviews on its append-only log (Oct 12, 2026), and the loop under construction will finally measure which findings were real, keep the findings and their outcomes as a labeled corpus in git, and learn from them with a local, trainable classifier — runs on your machine, nothing leaves it, $0 a call, abstains when unsure. One rule holds all of it: the classifier helps the gate see; it never helps the gate vote.
08Frequently asked questions
The short answers, in the shape engines can lift.
What is Turbo Rig?
Turbo Rig is a DevOps tool for AI coding agents: a cross-model AI code-review gate, git-versioned agent memory, and a written constitution that governs how AI coding agents build and ship software.
Is Turbo Rig free?
Yes. The rig is a thin layer of bash and Python scripts plus a markdown constitution. You bring your own AI subscriptions (Claude, Codex, GLM-class tools); the rig orchestrates and reviews them.
How does Turbo Rig review AI-generated code?
Every change passes a cross-model gate: a model family different from the builder's reviews the diff read-only and must end with a parseable APPROVED or REVISE verdict. Deterministic checks — tests, type checks — run first and cost nothing.
Does builder ≠ reviewer really matter?
Measure it, don’t take its word. In the rig’s first audited week (Sept 14–21, 2026; gate live Sept 16), 687 of 868 gate verdicts were REVISE and 141 PRs still shipped, every merge held by a human — a rig invariant, not a promise. Whether cross-family review beats same-family wasn’t measured that week; the verification dossier re-derives every number and states its limits.
Which AI tools does Turbo Rig work with?
Any headless CLI: ZCode, Claude Code, Codex, Grok, Gemini and others — builders and reviewers are swappable lanes. The one rule: the reviewer is never from the builder's model family.
Does Turbo Rig replace my AI coding assistant?
No. Agents still write the code. Turbo Rig governs them — verification, isolation, memory, and a human-held merge button.
My problem isn't writing code — it's reviewing it. Is this for me?
That's the exact lane. The gate is the reviewer you can't be for every line: it reads all of it, every time, fails closed when the verdict is missing or unparseable — and you keep the merge.
How is Turbo Rig different from agent sandboxes and agent platforms?
Turbo Rig is a DevOps tool that lets you pick the harnesses you want to work with — any headless CLI — and connects them together, each used for a different job: in the reference rig, one harness owns main and development while the other two handle review and testing. Each harness keeps its own individual rules; the rig wires them into one loop. Sandboxes and platforms prescribe their own runtime: their sandbox, their agent stack. The rig isn't a runtime to adopt — bash and python3, your repos, your merge button.